Introduction
Every time a music app queues up a song you turn out to love, or a shopping site shows a product matching one you just viewed, a nearest neighbour search has done the heavy lifting. Software represents songs, products, photos and sentences as vectors — lists of numbers called embeddings — and 'most similar' means the vectors closest to it. With millions of vectors, checking every one is far too slow. That is the problem Hnswlib was built to solve: it finds near-exact neighbours in milliseconds by searching a cleverly organised graph, not the whole dataset.
What Is Hnswlib?
Hnswlib is a lightweight, header-only C++ library implementing the Hierarchical Navigable Small World (HNSW) algorithm for approximate nearest neighbour search, with bindings for Python and several other languages. It was created by Yury Malkov, one of the authors of the original HNSW research paper, and is released under the Apache 2.0 licence, so it can be used freely in commercial projects. It is an in-memory indexing library, not a database: you load your vectors, build an index, and query it inside your own process, with no server to run.
How HNSW Works
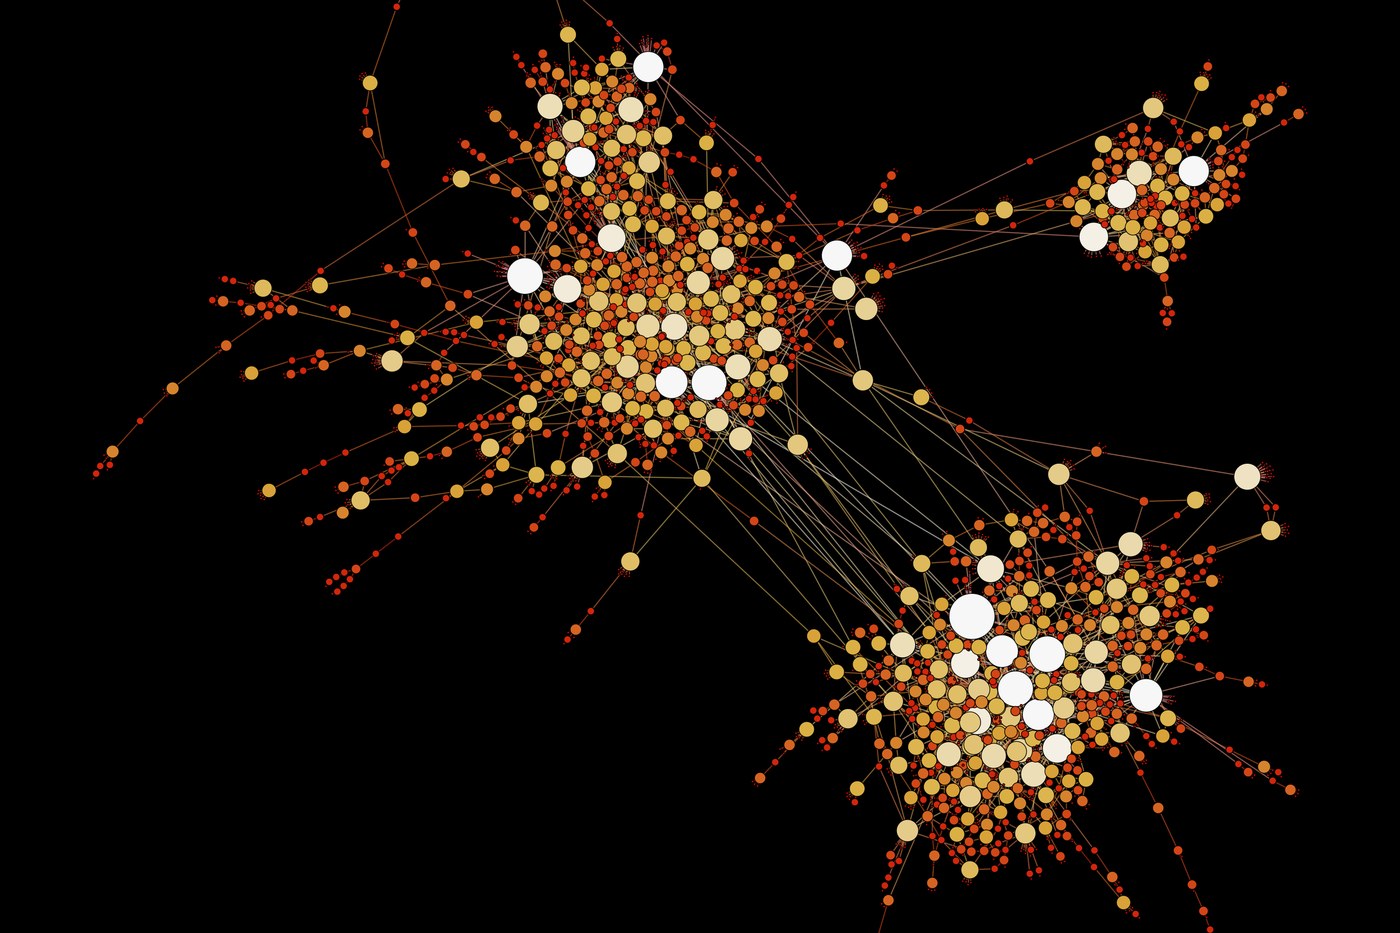
Picture the index as a graph. Every vector becomes a node, connected to a handful of its closest neighbours. Searching is like asking directions in a city: you start somewhere, repeatedly move to whichever connected node is closer to your destination, and stop when no step improves your position. Because nearby vectors are linked together, this greedy walk reaches the true neighbourhood of a query after surprisingly few hops.
Layers Act Like an Express Map
A flat graph still forces long walks across distant regions, so HNSW stacks several graphs into layers. The bottom layer contains every vector, with short links between close neighbours. Each higher layer keeps only a random subset of points, connected by much longer links. Search begins at the sparse top layer, where a few hops cover huge distances, then drops layer by layer, refining the position — motorways first, then main roads, then side streets.
Key Features
Speed is the headline feature. On standard suites such as ann-benchmarks, Hnswlib regularly sits at or near the top for recall against queries per second, returning 95 to 99 percent recall at speeds brute force cannot approach. It supports the metrics that matter in practice — L2 (Euclidean) distance, inner product and cosine similarity — and every vector can carry your own integer label as its ID. Indexes can be saved to disk and reloaded, elements added later, and deleted points marked for replacement. Building and querying are multithreaded.
Getting Started
Installing the Python package takes one command: pip install hnswlib. A minimal workflow has three steps. First, create an index for your metric space — 'l2', 'ip' or 'cosine' — with your vectors' dimensionality and maximum element count. Second, initialise the index with parameters such as ef_construction and M, covered below, then add your data with add_items together with their IDs. Third, call knn_query with query vectors to receive the labels and distances of the nearest neighbours. save_index and load_index persist the structure between runs.
The Three Parameters That Matter
Three numbers control most of Hnswlib's behaviour. M is the maximum number of connections each node keeps; higher values improve recall and speed on high-dimensional data at the cost of memory. ef_construction controls how carefully the graph is built — a larger value produces a better-connected index but takes longer to create. ef is set at query time and controls search width; raising it trades latency for recall. ef can be changed without rebuilding, so it is the knob teams tune first.
Where Hnswlib Is Used
Vector Search and AI Embeddings
The most common modern use is searching embeddings produced by machine-learning models. Text, images, audio and user behaviour can all be embedded into the same kind of vector space, and Hnswlib retrieves the closest matches fast enough for interactive products. It frequently appears inside retrieval-augmented generation (RAG) pipelines, where a language model's answer is grounded in the most relevant documents, and inside semantic search engines that match meaning rather than keywords.
Recommendations and Similarity Matching
Recommendation systems embed users and items and then look for close pairs: people with similar taste, products that resemble one another, songs in the same neighbourhood of style. Hnswlib powers that lookup directly, and the same machinery handles near-duplicate detection for images and documents, fraud checks that flag transactions close to known bad patterns, and entity matching across messy datasets.
Hnswlib Compared with Other Approaches
Exact search is simple and always correct, but its cost grows linearly with dataset size, ruling it out beyond a few hundred thousand vectors. Tree-based methods such as KD-trees degrade badly in high dimensions. Other libraries trade off differently: FAISS offers a huge toolbox including GPU indexes but is a much larger dependency; ScaNN and Annoy optimise for particular regimes. Hnswlib's niche is being small, dependency-free and extremely fast for in-memory workloads, and it is embedded inside several larger vector database products.
Frequently Asked Questions
Is Hnswlib free to use?
Yes. Hnswlib is open source under the Apache 2.0 licence, so you can use, modify and distribute it in commercial products without licence fees.
How accurate is approximate search?
Accuracy is measured as recall — the fraction of the true nearest neighbours the search returns. With sensible parameters, Hnswlib typically reaches 95 to 99 percent recall while running orders of magnitude faster than exact search, and recall can be pushed higher by increasing ef.
How much memory does an HNSW index need?
Memory is roughly the vectors themselves plus the graph links: about M connections per element on the base layer. A million 128-dimensional float vectors need around 512 MB for the data plus a few hundred MB more for the graph, depending on M.
Can Hnswlib update an existing index?
Yes. You can add new elements after the initial build, mark deleted ones so their slots can be reused, and optionally allow replacements. For very large changes, rebuilding from scratch is usually simpler and keeps the graph optimally connected.
Conclusion
Nearest neighbour search is the quiet engine behind search, recommendations and modern AI features, and Hnswlib remains one of the fastest and simplest ways to add it to a project. Its layered graph turns a scan of millions of vectors into a short, guided walk, and it runs happily inside an application rather than beside it. If you build anything that compares vectors — embeddings, recommendations, deduplication or retrieval — the documentation and examples at hnswlib.com are the natural place to start.
